Ask an operations director what they think of the analytics platform and you will usually get a diplomatic answer. Ask what they actually use to run the operation and they will show you a spreadsheet. This is not technophobia. It is a rational response to a decade of analytics projects that produced beautiful dashboards answering questions nobody had asked. The pattern repeated so consistently that it became a genre: a data warehouse programme, a visualisation tool, a portal of twenty dashboards, an enthusiastic launch, and a usage report six months later showing that four people log in weekly and three of them work in IT. The standard diagnosis is poor user adoption or insufficient training. That diagnosis is wrong often enough to be worth challenging directly.
Why Operational Leaders Reject Dashboards
The objection is almost never to data. Operations people are among the most numerate managers in any organization — they run capacity models, track throughput and argue about variance constantly. The objection is to a particular format, and the reasons are specific. Dashboards show state, and operations runs on change. A gauge showing 94% on-time delivery tells the manager what is already known. What matters is that it was 97% last week, that the drop is concentrated in one route, and that the cause is a supplier who changed their cut-off time. Dashboards are good at the first and poor at the other three. Aggregation removes the actionable layer. Operational intervention happens at the level of a specific order, shipment, invoice or customer. A departmental average is not something anyone can act on. The dashboard shows the temperature; the manager needs the list. The latency is wrong for the decision. A metric refreshed overnight is fine for a monthly review and useless for a decision that has to be made at ten in the morning. Many dashboards are built on a warehouse refresh cycle designed for finance reporting, and then offered to operations as if the timing were incidental. The numbers do not reconcile. The dashboard says one thing and the operational system says another, usually because of a definition difference — what counts as "shipped", whether cancellations are excluded, which timestamp is used. Once a manager finds one discrepancy they cannot explain, the whole platform loses credibility permanently. This single mechanism kills more analytics investments than any technical failure. Nothing happens as a result. The dashboard is looked at, the number is noted, and no process routes anything to anyone. A report that does not create an action is an observation, and busy people stop making optional observations.
What Operational Analytics Should Look Like Instead
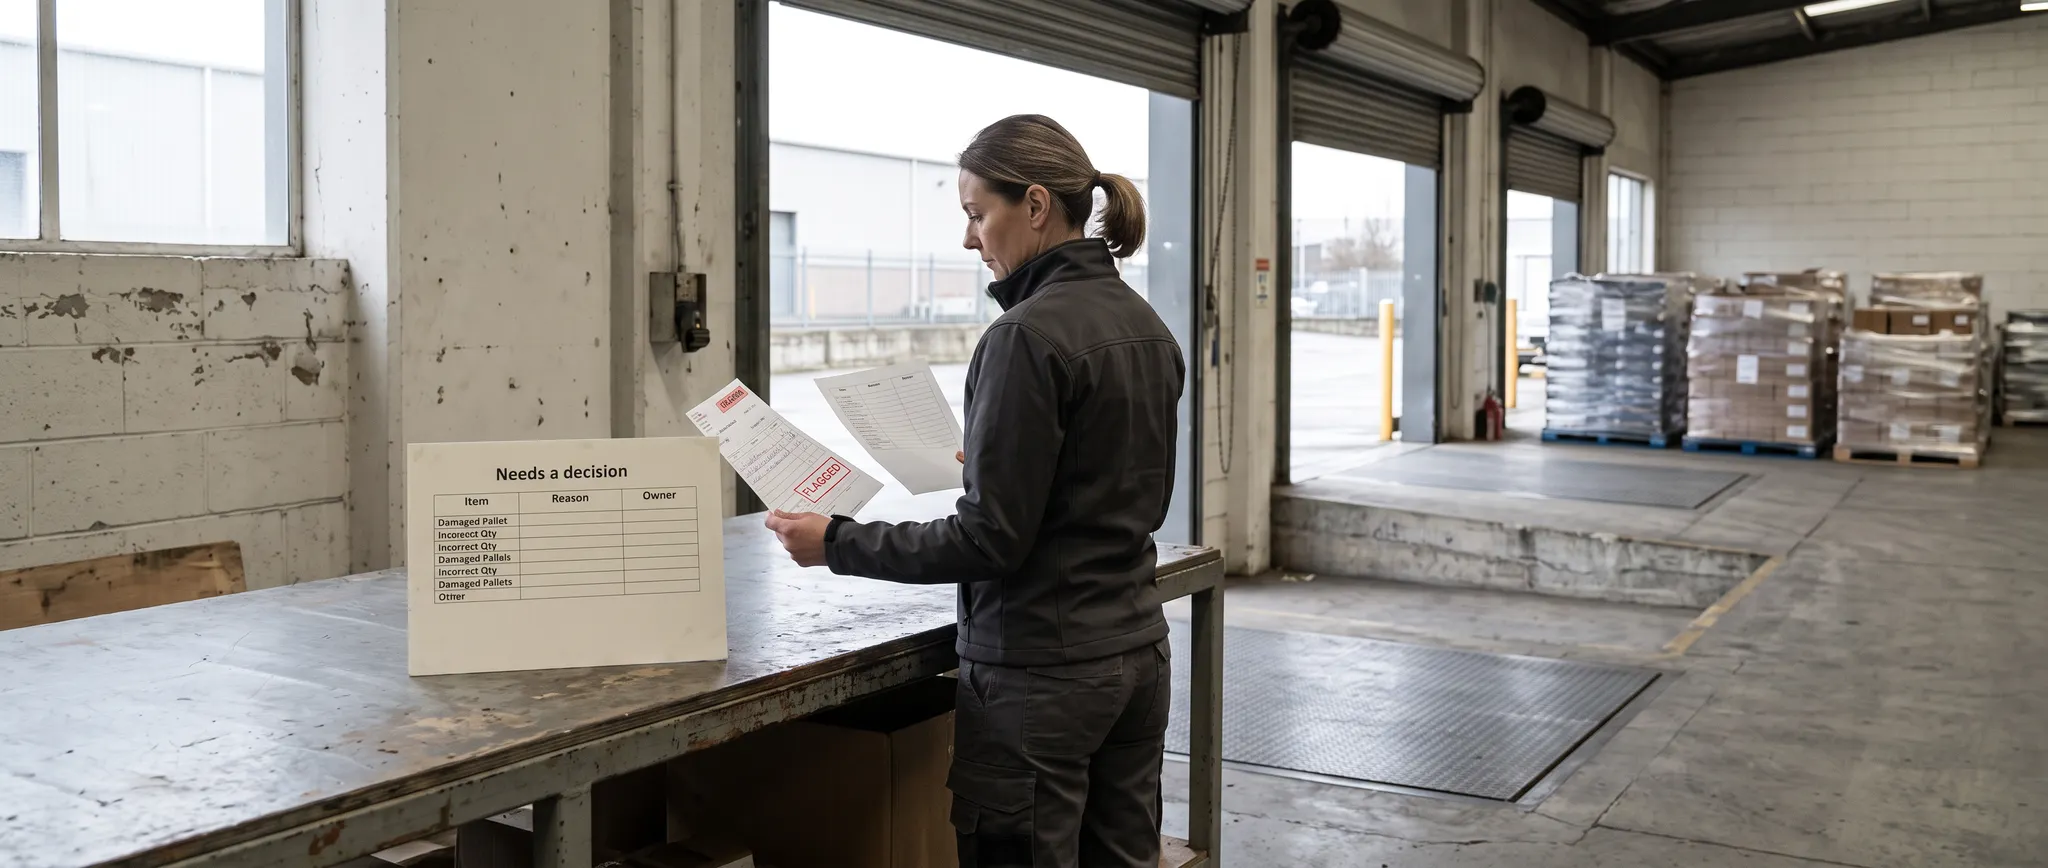
The alternative is not more dashboards or better ones. It is a different output format. Exceptions, not summaries. Do not show that 6% of deliveries were late. Show the forty-three that were, with the reason code and the account manager. The relevant unit of operational information is a row, not a ratio. Push, not pull. Operational staff will not log into a portal to check whether anything needs attention. Deliver the exception list to the place where work already happens — email, a messaging channel, the operational system's work queue. Comparison and trajectory by default. Every number should arrive with its prior period and its direction. A figure without context is not information. One authoritative definition, documented and visible. Every metric needs a written definition and a stated source, available to anyone who questions the number. This is what protects credibility when the inevitable discrepancy conversation happens. Matched to the decision cycle. If the decision is daily, the data must be daily. If it is hourly, overnight refresh is a non-starter. Build the refresh around the decision rather than around the warehouse schedule. Diagnosis paths, not just measurement. When the number moves, the next question is always why. Being able to break the metric down by route, customer, shift or product without raising a request is the difference between a report and a tool.
The Case for the Spreadsheet
It is worth conceding what the spreadsheet does well, because the analytics profession has spent twenty years trying to eliminate it and has largely failed. The spreadsheet is fast to modify, requires nobody's permission, handles the specific question being asked today, and can be annotated, filtered, sorted and sent to a colleague without a governance conversation. It bends to the user rather than requiring the user to bend to it. That flexibility is genuinely valuable, and the managed analytics platform frequently has none of it. What the spreadsheet lacks is reconciliation, version control, auditability and any guarantee that two people using it are looking at the same thing. Those are real problems and they justify investment in something better. But the replacement has to win on the dimensions the spreadsheet actually wins on — speed, flexibility, specificity — and most platform deployments do not compete there at all.
| Reporting question | Useful output |
|---|---|
| What needs attention? | Specific exception items, reason and owner |
| What changed? | Prior-period comparison and a diagnosis path |
| Can I trust this number? | A written definition and authoritative source |
| Is it current enough? | Refresh matched to the decision cycle |
| What happens next? | Delivery into an existing work queue |
Qualitative summary of this article's source text, not a measured outcome or performance estimate.
Practical Guidance for Operational Analytics
- Start from decisions, not from data. List the ten recurring operational decisions and what information each requires. Build for those. A dashboard built from available data rather than required decisions will answer questions nobody asked.
- Deliver exception lists rather than aggregate metrics. Name the specific items that need attention, with owner and reason. This is the single change that most reliably converts an ignored report into a used one.
- Push into existing workflow. A daily exception list arriving where work already happens beats a portal with better visualisations that requires a deliberate visit.
- Publish metric definitions before publishing metrics. Written, versioned and accessible. The first unexplained discrepancy determines whether the platform survives.
- Match refresh frequency to the decision, not to the warehouse. If that requires a direct operational feed rather than a nightly warehouse load, build it that way.
- Include a drill path to the transaction. A manager must be able to get from the number to the underlying rows without asking anyone. Without this, every anomaly becomes a request and the analytics team becomes a bottleneck.
- Measure the report, not the platform. Track which reports are actually opened and which drive action. Retire the rest — an analytics estate accumulates unused content exactly like a close checklist accumulates unnecessary steps.
- Ask what people currently maintain by hand. The spreadsheets that operational managers build themselves are a precise, validated specification of what the platform failed to provide.
Why This Is Getting More Urgent
The consequences of unusable operational reporting used to be modest: managers maintained their own spreadsheets, the numbers diverged slightly, and the organization absorbed the inefficiency. Two changes have raised the stakes. Operating margins in logistics, contracting, retail and services have tightened to the point where operational variance that was previously tolerable is now the difference between a profitable contract and an unprofitable one. And AI-driven analysis has made it trivially easy to produce a confident narrative from whatever data is available — including data with inconsistent definitions, stale refreshes and unreconciled sources. That second change is the significant one. For years, the check on bad operational data was a manager who knew the operation well enough to say "that number is wrong" and go and look. As analysis is increasingly generated rather than constructed, that check is applied less often and later. The definitional discipline that seemed like bureaucratic overhead in the dashboard era has become the thing that determines whether the automated layer above it produces sense or nonsense. The operations directors who kept their own spreadsheets were not being difficult. They were maintaining the only version of the numbers they could personally verify — and that instinct is worth more now, not less.
Common Questions
Why do operational managers ignore dashboards?
Because dashboards typically show aggregated state rather than the specific items requiring action, refresh on a cycle built for finance rather than operations, lack context and trajectory, and produce numbers that do not reconcile with the operational system — which destroys trust permanently.
What is the difference between a dashboard and operational reporting?
A dashboard presents summarised metrics for monitoring. Operational reporting names the specific exceptions requiring attention, delivers them into the workflow where work happens, and provides a path from the number to the underlying transactions.
Why do spreadsheets keep winning?
Because they are immediately modifiable, answer the specific question being asked today, and require no one's approval. Any replacement has to compete on speed, flexibility and specificity, which most managed platforms do not attempt.
How do you rebuild trust after users stop believing the numbers?
By publishing written, versioned metric definitions with stated sources, reconciling explicitly to the operational system, and making the drill path to underlying transactions available so that any discrepancy can be investigated without raising a request.
Operational Reporting Redesign — Outpace starts from the decisions your managers actually make, then builds exception-driven reporting they will use instead of their spreadsheets.