Every vendor conversation this spring ends the same way. The capability is impressive, the demonstration went well, and then comes the closing line: your own data is your competitive advantage, and this is how you finally use it. The principle is sound. The problem is that back office data estates were built to survive an audit and close a month, not to teach anything. What was captured is the outcome of each decision, in a structure designed for reporting periods, with the reasoning discarded at the point of entry.
Your systems recorded what was decided. They almost never recorded why, and the why is the part a model would need
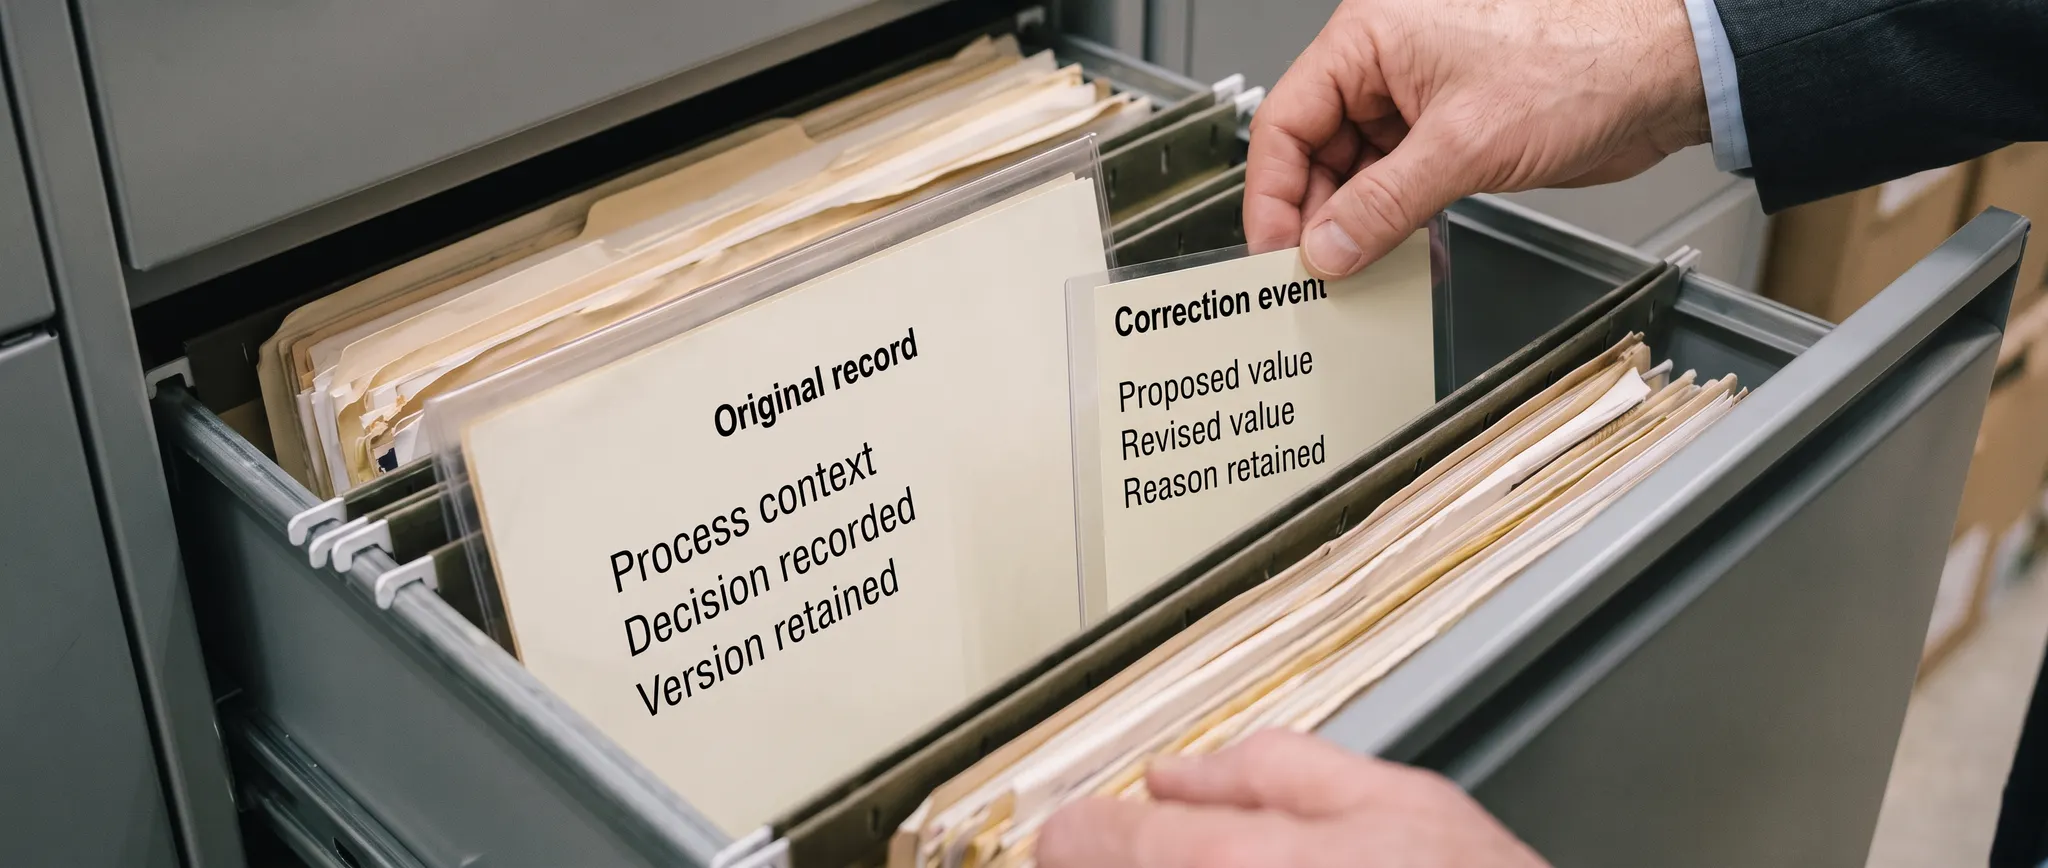
A general ledger contains millions of postings and almost no information about judgement. The accrual is there; the argument about whether it was the right amount is not. The invoice was coded to a cost centre; the fact that the first coding was wrong and someone corrected it three weeks later is usually invisible, because the correction overwrote the original rather than being recorded as a second event. This is the gap between having data and having a dataset. Volume is abundant in every back office. Information density is much scarcer, and it is concentrated in places nobody currently treats as systems of record.
Four categories, ranked by how ready they actually are
Structured transactions. Ledger entries, invoices, payments, payroll runs. Clean, plentiful, well governed and low in information density. Useful for pattern detection and anomaly work, close to useless for anything requiring context. Documents. Contracts, invoices as received, policies, statements, correspondence with authorities. High value, poor structure, scattered across shared drives, mailboxes and archive systems. This is where most of the genuine institutional knowledge sits. Process exhaust. Workflow logs, approval chains, timestamps, rejections and reassignments. Comprehensively underrated, because it is the only record of how work actually moves rather than how the process documentation says it moves. Correspondence. Email and chat threads in which the reasoning actually happened. Highest reasoning content by a distance, and the worst governance position of any category, which is why sensible organisations approach it last.
The asset nobody counts
Process exhaust deserves particular attention because it is already captured, already retained and almost never examined. Approval timestamps show where work waits and for whom. Rejection and resubmission patterns show which controls are real and which are rubber stamps. Reassignment chains show who actually decides, as opposed to who is named in the delegation matrix. An organisation that mines three years of its own workflow logs will learn more about its operating model in a fortnight than it will from any amount of language modelling over its ledger. It is also the safest place to start, because it contains no customer data and very little personal data beyond employee identifiers.
Five properties that constitute readiness
Identity. Can an entity be joined across systems reliably, or does the same supplier exist as four records with four spellings. Outcome labels. Do you know which decisions turned out to be wrong. Temporal integrity. Are records effective-dated and corrections recorded as events, or does the current state overwrite the history. Retrievability. Is the document in a system with an interface, or in somebody's mailbox, or in a carton. Rights. Do you have a defensible basis to use this material for a purpose other than the one it was collected for.
| Property | Question to answer |
|---|---|
| Identity | Can the same entity be joined across systems? |
| Outcome labels | Can later corrections be linked to decisions? |
| Temporal integrity | Are effective dates and earlier versions retained? |
| Retrievability | Can the authorised document be retrieved? |
| Rights | Is the proposed use supported by a documented basis? |
Qualitative summary of this article's source text, not a measured outcome or performance estimate.
The label problem is the one worth solving first
Most back office functions have millions of examples and no labels. You have a million coded invoices and no systematic record of which codings were later corrected. You have thousands of approved expense claims and no record of which ones the audit later challenged. Without labels there is no way to evaluate any model, which means there is no way to know whether an assistant is helping or quietly degrading the quality of the work. The fix is cheap and compounds. Start recording corrections as first-class events from now on: what was proposed, what it was changed to, by whom, and why, in a structured field rather than in free text. Six months of that is worth more than twenty years of unlabelled history, and it costs a configuration change rather than a programme.
What not to do
Do not start a data lake project whose first deliverable is eighteen months away. Do not launch a master data programme that must finish before anything else can begin. Do not buy a platform whose value proposition is readiness itself. Each of these is a way of converting an uncomfortable question into a reassuring budget line, and none of them produces a usable dataset faster than picking one process and fixing its identity keys and its labels.
Practical Guidance for Data Readiness Assessment
- Start with process exhaust, which you already have and never look at.
- Fix identity keys for suppliers, customers and employees before anything else.
- Record corrections as events, not as overwrites.
- Capture outcome labels from today, even if history has none.
- Establish language of record for every contract and filing.
- Document the lawful basis for any secondary use, before the pilot.
- Digitise selectively, where a live use case meets a retention duty.
- Refuse readiness programmes without a named first use case.
The Regional Angle
Three factors make this materially harder, and in one respect easier, for groups operating here. The first is that the right to use your own historical data is less settled than most regional executives assume. Data protection regimes across the Gulf have moved from drafting to operation over the past year, with Saudi enforcement having commenced last month and the Emirates still awaiting executive regulations that will define the detail. Using records collected for payroll, recruitment or customer servicing to train or tune a model is a secondary purpose, and secondary purposes generally need a basis that nobody documented at the time. Employee data is the sharpest case in this region, because a large share of it belongs to people who have left the country and whose employment ended years ago. The practical step is to segment the corpus by data subject type before anyone touches it, treat human resources records as out of scope until a lawyer has written down the basis, and start with process exhaust and corporate documents where the question barely arises. The second is a hazard specific to bilingual estates, and it is one that retrieval systems handle badly. In much of the region the legally binding version of a contract, a government notification, a labour filing or a tax ruling is the Arabic text, and the English document sitting in the shared drive is a convenience translation prepared by someone in the business. A retrieval system indexing whatever it finds will answer questions about obligations from the translation, fluently and with no indication that it is quoting a document with no legal standing. Worse, translations drift; the English version may reflect a superseded draft. Mark language of record at the document level, make the binding version the one that is indexed for anything contractual or regulatory, and treat translations as secondary references that the system is instructed to caveat. The third is the physical archive, and this is where regional groups routinely overspend. Decades of invoices, contracts, customs paperwork and personnel files exist as paper or as scanned images in offices across several countries, subject to retention rules that differ by jurisdiction and by document class. The instinctive response to an AI initiative is to digitise everything, which is a large, slow and almost entirely wasted expenditure. Almost none of that archive has a use case. Digitise where a live use case and a retention obligation overlap, in that order, and leave the rest where it is. The organisations that get value this year will be the ones that processed four thousand relevant documents properly rather than four million indiscriminately.
The objection worth taking seriously
The strongest objection is that fix your data first is the oldest delaying tactic in enterprise technology. It has justified two decades of warehouse projects, master data programmes and governance initiatives that delivered architecture diagrams and no capability, while the business waited. And it is now technically outdated: current models are considerably more tolerant of messy input than the systems that generated this orthodoxy, retrieval over imperfect documents genuinely works, and the organisations extracting value this year are the ones that pointed something at their messy estate and started learning, rather than the ones sequencing a readiness programme ahead of any use. That critique lands, and the tolerance argument is correct for a specific and important class of work: retrieval, summarisation and drafting, where a human reads the output and the cost of an occasional bad answer is low. It does not extend to automated decisioning, where an unlabelled dataset means you cannot measure whether the system is right, and an inconsistent identity key means you cannot tell whether two records describe the same counterparty. Nor does it justify inaction, because the two recommendations that matter here are not programmes. Establishing a single identity key for suppliers and starting to log corrections as events are weeks of work, not years, and they are the difference between a pilot that can be evaluated and one that will be judged on whether the demonstration felt impressive.
Common Questions
Do we need a data warehouse before we can do any of this?
No. Retrieval works against documents where they sit, and process exhaust can be extracted from workflow systems directly. A warehouse helps with analytics; it is not a prerequisite for a first use case.
How much history do we actually need?
Less than you think, and more recent than you think. Two years of well-labelled, correctly joined records will outperform twenty years of unlabelled history in almost every back office application.
Is our data valuable enough to be a differentiator?
Your transactions probably are not, because your competitors have similar ones. Your process exhaust and your contract estate might be, because they encode how your organisation specifically works.
What should we expect over the next twelve months?
Expect every enterprise vendor to ship a use-your-own-data feature this year, nearly all of it retrieval over existing content rather than anything trained on your records. Expect the governance questions to arrive attached to those features, and to be answered badly at first. Expect regional regulators to begin asking about secondary use of personal data as their enforcement functions mature. And expect the organisations that pull ahead to be distinguished by labels and identity discipline rather than by data volume, which is fortunate, because volume is the one thing nobody is short of.
Data Readiness Assessment — we find the assets you already hold and never look at, fix identity and labelling where it changes outcomes, and stop the digitisation programme you do not need.