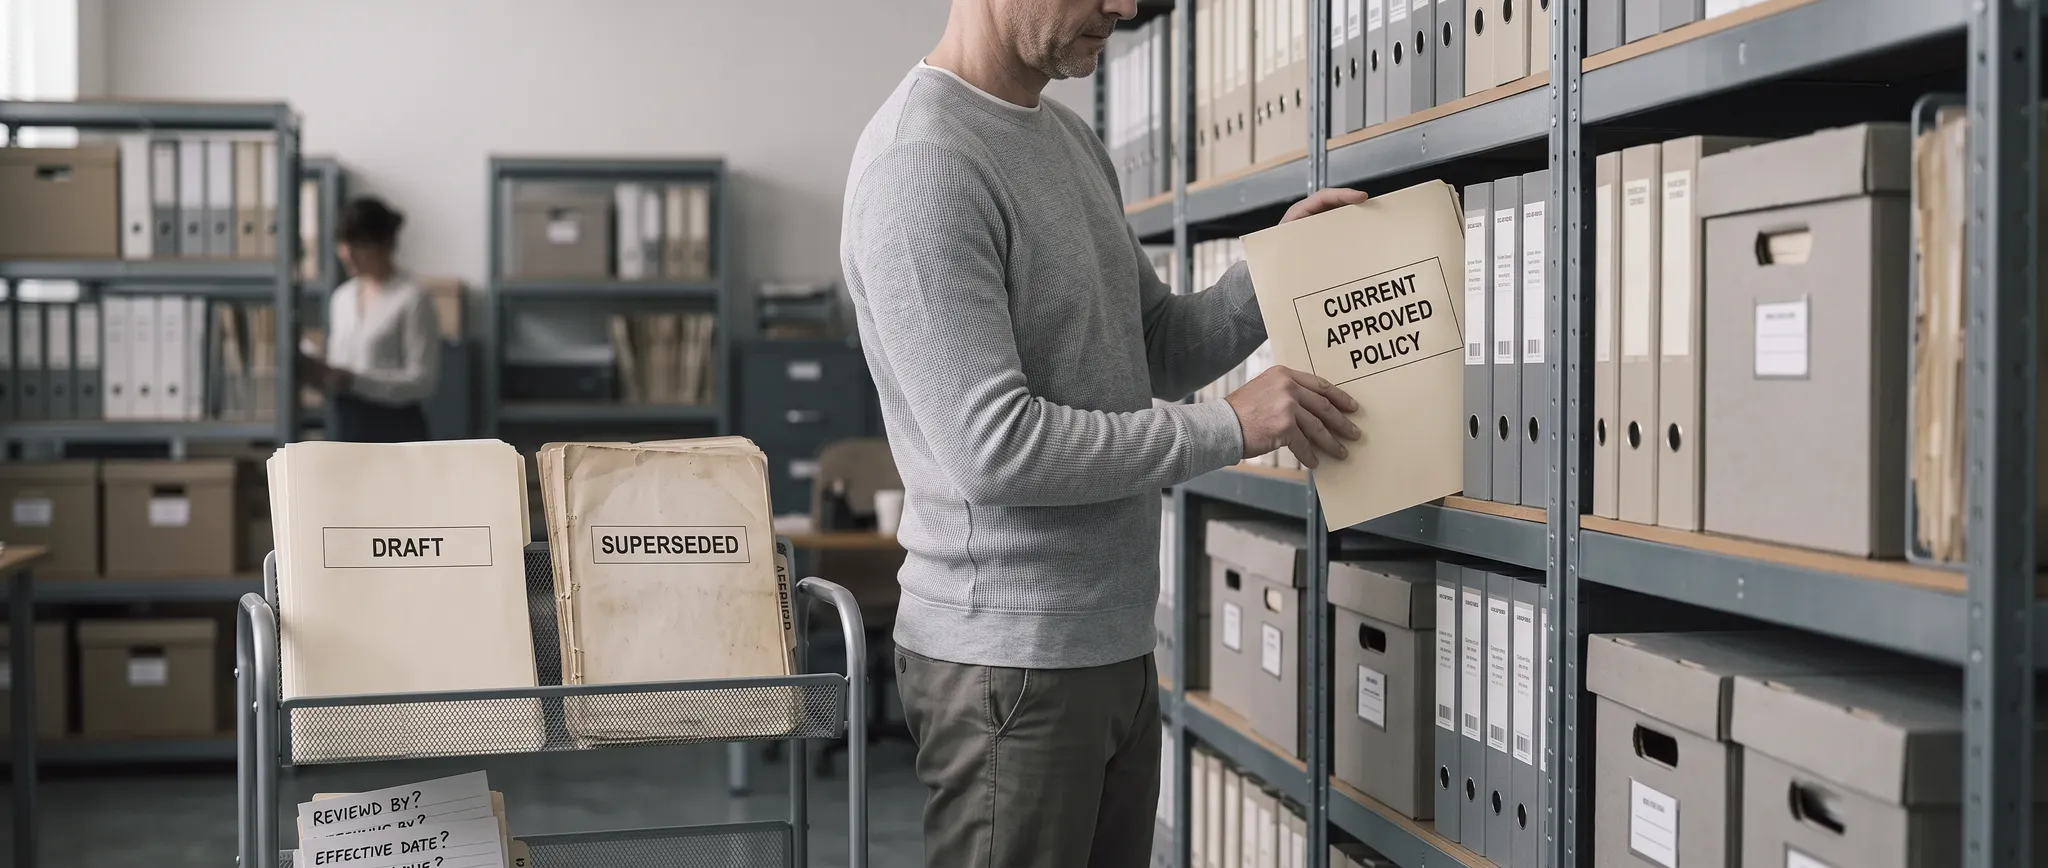
The discipline that started the year being called prompt engineering has quietly become something else. The instruction was never the hard part; anyone can write a clear request. What determines whether an assistant produces a usable answer is what sits in front of the model at the moment it answers — which documents, which recent decisions, which definitions, which of the four conflicting versions of the policy. That is an information architecture problem wearing a machine learning costume, and it is being handed to teams who have no mandate to solve it.
Nobody's assistant is underperforming because the prompt was badly worded. It is underperforming because the organisation never decided which document is the real one
Here is what context engineering actually consists of, and why the work is organisational rather than technical.
The four decisions that determine output quality
Which sources are authoritative. Most organisations hold several versions of every important document — a draft, a superseded version, a team's local copy, and the approved one. A human asking a colleague gets the right one by social routing. An assistant reading all four averages them, which is worse than picking wrong. What gets excluded. Counterintuitively, this matters more than what gets included. Old material, abandoned proposals and superseded policies are the dominant source of confidently wrong answers, and they look exactly like current material to a retrieval system. How much fits, and in what order. Context windows are large now and that has made people careless. Filling the window with marginally relevant material measurably degrades answers; the useful discipline is fewer, better passages. What structural signal travels with the content. A passage stripped of its date, author, status and parent document is nearly useless for judging authority. Most retrieval pipelines discard exactly that metadata.
Why this cannot be solved by the technology team
Deciding which document is authoritative is a governance act. It means someone must declare that this version supersedes that one, that this team owns this definition, and that the old page is archived rather than left in place because someone might still need it. That is not a decision an engineer can make, and it is the reason retrieval projects stall at a demonstration. The demonstration works because it was pointed at a curated set. Production fails because it was pointed at the real one.
A sequence that works
Start from the questions rather than the corpus. Collect the forty questions people actually ask, find the authoritative answer for each one, and note where no authoritative answer exists — that list is the real deliverable, because those gaps were failing your staff long before any assistant existed. Then mark the sources that answer those questions as authoritative, archive their competitors properly, and preserve dates, owners and status through the retrieval pipeline. Measure on the forty questions, not on impressions.
Collect the questions
Use requests people actually make and record unanswered ones.
Decide authority
Name the source and business owner allowed to answer each question.
Preserve context
Carry date, owner and status with the selected passages.
Recheck answers
Evaluate against the same real questions as sources change.
Qualitative summary of this article's source text, not a measured outcome or performance estimate.
Practical Guidance for Context Architecture Review
- Start from real questions, not from the document set.
- Declare authoritative sources explicitly and record who decided.
- Archive superseded material; do not leave it readable.
- Preserve date, owner and status through the pipeline.
- Prefer fewer strong passages over filling the window.
- Treat unanswerable questions as findings, not failures.
- Give the corpus an owner with authority to archive.
- Re-measure quarterly; authority decays as the business changes.
The Regional Angle
The first factor here is bilingual content, which breaks retrieval in a way that is easy to miss. Regional organisations hold policies, contracts and government correspondence in Arabic and English, often as parallel documents that are not quite equivalent, and frequently with the Arabic version governing legally while the English version is the one people read. A retrieval system asked a question in English will find the English document and answer confidently from the version that does not govern. Decide explicitly, per document class, which language version is authoritative, and make sure the pipeline can retrieve across languages rather than only within the language of the question. The second concerns where the authoritative content actually lives in regional enterprises, which is often not in the document system at all. A great deal of operative knowledge here sits in email threads with a bank or a ministry, in messages on a chat application used for real coordination, and in PDFs of stamped and signed originals whose text layer is an image. None of that is reachable by a retrieval pipeline pointed at the intranet, which means the assistant will answer from the written policy while the organisation operates from the correspondence. The practical move is to identify the three or four processes where the real answer lives outside the document store and either bring that material in deliberately or scope the assistant to exclude those topics. The third is about who is empowered to declare a document authoritative, which is a structural obstacle in this region more than a procedural one. In family-owned groups and owner-led businesses, authority over a policy often rests with an individual rather than a committee, and no formal document governance role exists; middle managers cannot archive a superseded procedure because nobody is certain whether it was ever formally replaced. That produces exactly the accumulation of parallel versions that defeats retrieval. The fix is not a governance framework — it is getting a single named decision-maker to spend two sessions declaring, for the twenty most-asked topics, which document is current. That is achievable in a fortnight and it is worth more than any tuning.
The objection worth taking seriously
The strongest objection is that this is a temporary problem being elevated into a permanent discipline. Context windows have grown by an order of magnitude in two years and models have become markedly better at handling conflicting and irrelevant material; the careful curation being prescribed here is an accommodation to current limitations that will look quaint when a model can simply read everything and reason about which version is current from the dates and the language. Investing in a context engineering practice now is building scaffolding for a building that is about to get taller on its own. The trajectory is real — models have absorbed much of what used to require careful retrieval design, and some of the tuning work of eighteen months ago is genuinely obsolete. But the part being recommended here is not the part that gets absorbed. A larger window and a better model can rank and reconcile, and they still cannot know that the December version was approved while the January draft was abandoned in a meeting, because that fact exists nowhere in the text. No amount of capability recovers information the organisation never recorded. What improves is tolerance for messy inputs; what does not improve is the absence of a decision about which document is real. That is why the recommendation is deliberately not about chunking strategies or embedding models — those will date. Declaring authority, preserving status metadata and archiving properly are durable, and they would be worth doing if no assistant existed at all.
Common Questions
Is this different from knowledge management?
It is knowledge management with a consumer that cannot use social cues to find the right answer. The discipline is old; the tolerance for skipping it has gone.
How many questions should we benchmark against?
Forty to sixty real ones, collected from actual requests rather than invented. Enough to detect regression, few enough that someone will maintain them.
Who should own the corpus?
Someone in the business with authority to archive documents, not the technology team. Ownership without the power to remove content is not ownership.
What should we expect over the next twelve months?
Expect the vocabulary to keep shifting as vendors rename the same work. Expect platform-native retrieval to improve enough that most organisations stop building their own. Expect the failure mode to remain stale authoritative sources rather than model quality. And expect the organisations that fixed their document hygiene to get disproportionate benefit from every subsequent model upgrade.
Context Architecture Review — we find the questions your teams actually ask, then settle which document is allowed to answer them.