Every privacy programme begins with the same discovery: nobody knows where the personal data is. Not in a vague sense — in the specific, enumerable sense of being unable to answer the question "if a customer asked us to delete everything we hold about them, which systems would we need to touch?" This is not negligence. It is the predictable result of twenty years of organic system growth. A CRM was purchased. A marketing platform was added. Analytics were installed. A support tool was integrated. A data warehouse was built to report across all of it. A finance team exported a list to a spreadsheet for a project in 2014 and it is still on a shared drive. An outsourced provider received a monthly file. None of it was designed as a whole, and nobody was ever assigned responsibility for knowing the shape of it. Then a regulation arrives requiring you to locate, produce, correct, delete, restrict and report on personal data, and the absence of a map stops being a documentation gap and becomes the constraint on everything else.
Why Every Privacy Obligation Depends on the Map
It is worth being explicit about the dependency, because data mapping is frequently treated as preparatory paperwork rather than as the load-bearing element. Subject access requests require finding every location holding data about one individual, within a statutory deadline, including systems that were never designed to be searched by person. Erasure requests require deleting from every location, including backups, warehouses, replicas and any processor you have shared with. An erasure that misses the data warehouse is not an erasure. Breach notification requires knowing, within 72 hours under most modern regimes, whose data was in the affected system and what categories it covered. Organizations without a map spend the first two days of an incident doing discovery instead of response. Lawful basis documentation requires knowing what processing occurs before you can justify it. You cannot record a basis for a processing activity you have not identified. Cross-border transfer compliance requires knowing which processors receive which data and where they operate. This is the single most common gap in regional compliance programmes. Retention requires knowing what you hold, so you can delete what has aged out. Most organizations have retention policies that describe data they cannot locate. Each obligation fails independently if the map is wrong, and the map is the only shared dependency. Which is why organizations that skip it end up building six partial answers instead of one complete one.
Where the Data Actually Hides
The systems everyone remembers are the CRM, the HR system and the ERP. The map fails because of the ones nobody lists. Backups and disaster recovery copies. Frequently the largest single hole in an erasure process. Deleting from production while thirteen months of backups retain the record is common and is not compliant, though most regimes accept a documented approach to backup deletion on the next restore cycle. Data warehouses and reporting layers. Personal data denormalised into an analytics environment, often with different field names, frequently with no link back to the source record. Email and shared drives. Attachments containing customer lists, payroll files, CVs and contracts. This is genuinely difficult to govern and is where a large share of unstructured personal data lives. Spreadsheets. A department extracted data for a project and kept the extract. There is no inventory of these anywhere, and they are usually discovered by asking people rather than by scanning systems. Logs and monitoring. Application logs containing identifiers, IP addresses, email addresses in error messages, session records. Retained for operational reasons, rarely covered by any retention policy. Third-party processors. Email delivery services, SMS gateways, payment processors, support platforms, survey tools, recruitment portals, benefits administrators, outsourced payroll. Each holds a copy. Each has its own retention, its own geography and its own subprocessors. Decommissioned systems. The application was replaced; the database was kept "in case we need history". It is still there, still holding personal data, and nobody owns it. Development and test environments. Production data copied into test, usually years ago, usually not masked, usually with wider access than production.
How to Build a Map That Stays Accurate
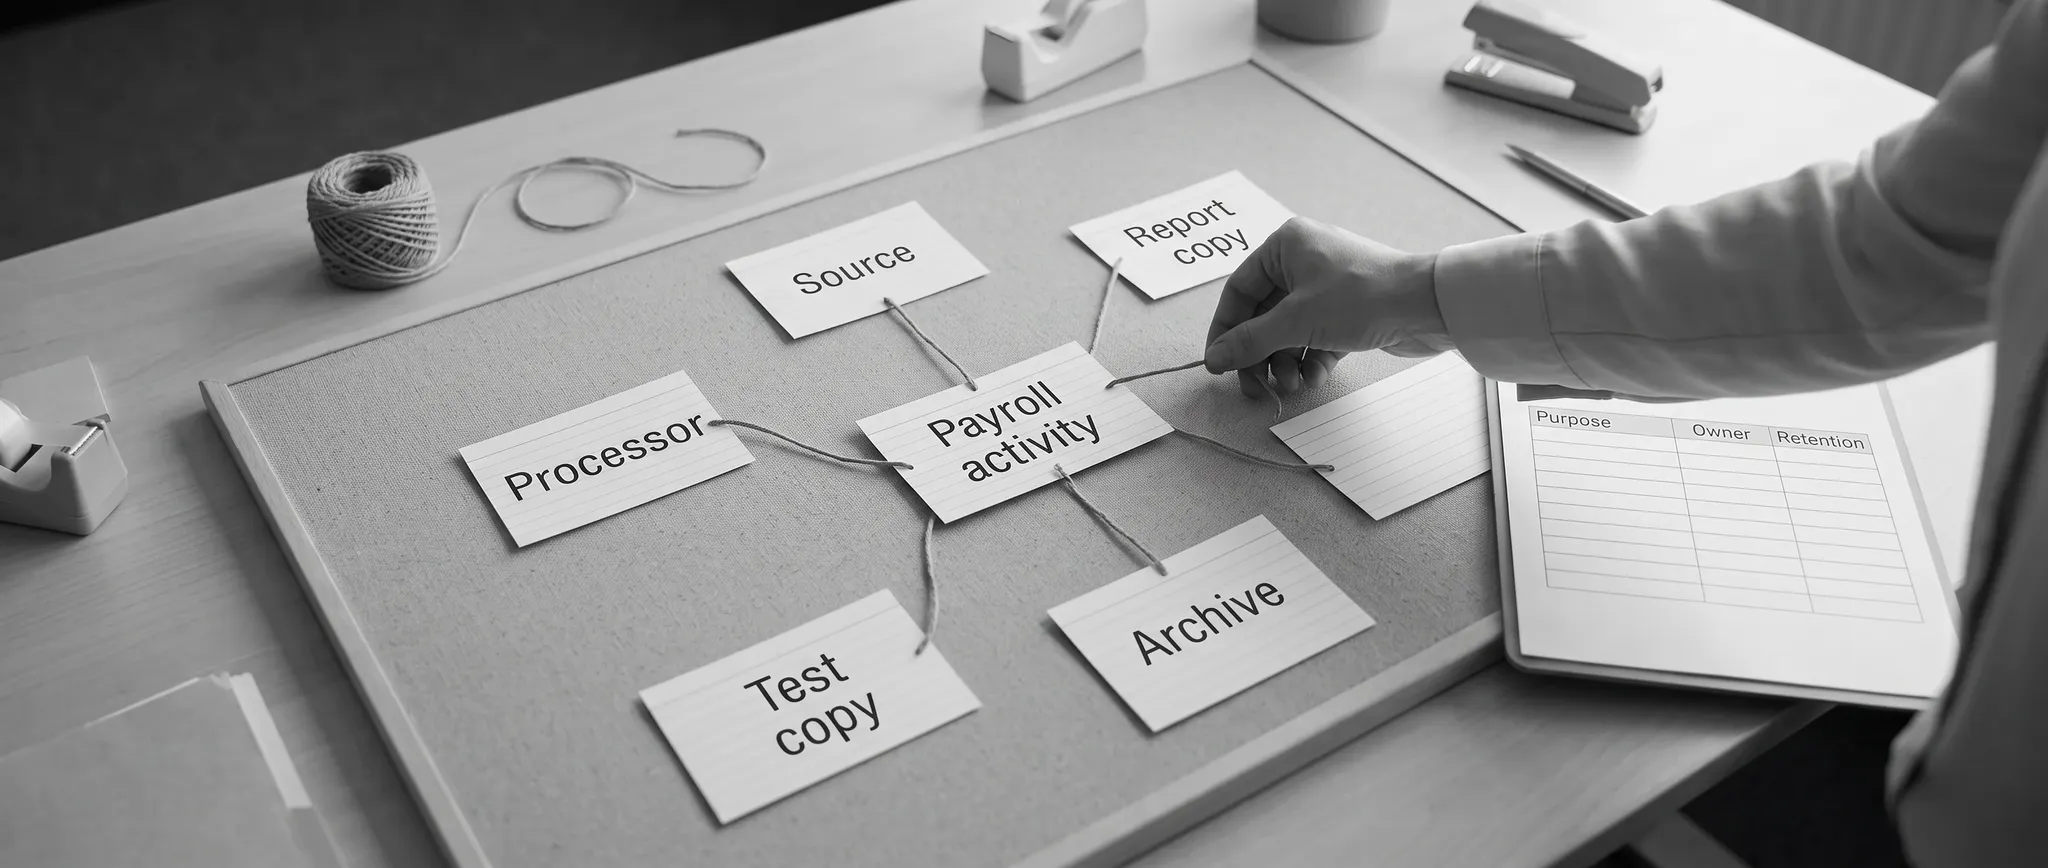
The failure mode of data mapping is not inaccuracy at the start. It is obsolescence. A map compiled by consultants and delivered as a spreadsheet is out of date within a quarter and abandoned within a year. Interview people, then verify technically. Ask each team what data they handle, what they receive, what they send and what they keep. This surfaces the spreadsheets and the informal flows that no scanning tool will find. Then verify against system inventories, database schemas and network flows, because what people believe happens and what happens differ. Map at the level of processing activity, not system. "Customer onboarding" or "payroll processing" — each with its purpose, data categories, subjects, lawful basis, recipients, transfers and retention. This is the structure regulators expect and it is more stable than a system list, which changes constantly. Assign an owner per activity. A named business owner, not IT. IT knows where data sits; only the business knows why it is held and whether it is still needed. Attach the map to change processes. New system procurement, new integration, new supplier, new report — each should update the map as part of approval. Without this hook, the map decays regardless of how good it was on day one. Start with high-risk and high-volume. Customer data, employee data, anything special category, anything moving across borders. A complete map of the important flows beats an incomplete map of everything. Use the exercise to delete. The most valuable output of a data mapping project is usually not the map. It is the list of data nobody needs, which can be deleted, reducing risk and obligation simultaneously. Most organizations find several systems and many extracts that exist for no current purpose.
Interview and trace
Find informal extracts as well as recognised systems and recipients.
Verify technically
Compare reported flows against schemas, system inventories and access.
Assign and maintain
Name an activity owner and update the register when procurement or flows change.
Rehearse a request
Test an end-to-end response and resolve the gaps with retention rules intact.
Qualitative summary of this article's source text, not a measured outcome or performance estimate.
Practical Guidance for Data Mapping
- Treat the map as the foundation, not the paperwork. Access requests, erasure, breach notification, transfer compliance and retention all depend on it and all fail independently without it.
- Interview before you scan. Automated discovery finds structured data in known systems. It does not find the export on a shared drive or the monthly file emailed to a provider.
- Map processing activities, not applications. More stable, more useful, and the format regulators actually ask for.
- Chase the copies deliberately. Backups, warehouses, logs, test environments, decommissioned databases and processor systems. Missing these is what turns a documented programme into a finding.
- Build a processor register with geography and subprocessors. Every third party, what it receives, where it processes, under what contract. This is the document that determines whether your transfer position holds.
- Delete aggressively as you go. Data you do not hold cannot be requested, breached, transferred or fined. Minimisation is the highest-return action available during a mapping exercise.
- Hook the map into procurement and change control. A map that is not updated by the processes that change reality is a historical document within months.
- Test it with a real request. Run a mock subject access and erasure request end to end. The gaps appear immediately and cheaply, which is much better than discovering them against a statutory deadline.
The Regional Complication
For Gulf-based groups, data mapping has a structural difficulty that generic guidance does not address: the same individual's data legitimately exists in several countries as a matter of ordinary business process. Consider a typical regional structure. Operating entities in the UAE, Saudi Arabia, Qatar and Egypt. A shared services centre handling finance and payroll for all of them, often in Egypt, India or the Philippines. Group consolidation and reporting in Dubai. An outsourced payroll provider per country because statutory requirements differ. Banking relationships per entity. HR records held both locally for labour law compliance and centrally for group reporting. An employee record in that structure exists in the local HR system, the group HR system, the payroll provider's system, the shared services team's working files, the bank's WPS submissions, the accounting system and the consolidation layer. Seven locations, at least four jurisdictions, and each flow needs a documented basis under the UAE framework and PDPL. Two further regional specifics are worth noting. Names frequently appear in both Arabic and English, with transliteration variants, which means the same individual may not be matchable across systems — a practical obstacle to both access requests and erasure. And the mobile, largely expatriate workforce means personal data includes passport, visa, Emirates ID and sponsorship information, which is both sensitive and distributed across more systems than most organizations expect. Groups that mapped this properly usually found that the map itself justified restructuring: consolidating entities, reducing the number of payroll providers, and eliminating duplicate HR systems. The compliance requirement paid for an operational simplification that had been deferred for years.
The Inventory Problem, Version Three
The same exercise is now required for AI, and most organizations are at the stage privacy programmes occupied in 2012 — aware that it will be necessary, unable to say how many tools are already in use. The questions are familiar. Which models and AI-enabled tools are running. What data each one receives. Whether that data is retained, logged or used for training. Which subprocessors sit behind each service. Where inference happens geographically. Whether any of them make or materially influence decisions about individuals. Who approved each one. The discovery problem is worse than it was for personal data, because adoption is faster, individual employees can introduce a tool without procurement, and AI features are being added to software that was approved years ago for other purposes. An organization can acquire two dozen new data flows in a quarter without anyone making a decision. The organizations handling this well are the ones extending the register they already built. The processing activity structure works: purpose, data categories, recipients, geography, retention, owner. An AI tool is another recipient of data, assessed the same way. Which is the durable argument for doing this work properly. A data map built for GDPR in 2016 served the regional privacy laws, then the localization requirements, and now the AI inventory. Three regulatory waves, one asset. Organizations that treated it as a compliance deliverable rather than an operational capability have paid for it three times.
Common Questions
Why is data mapping the foundation of a privacy programme?
Because every other obligation depends on it. Subject access, erasure, breach notification within 72 hours, lawful basis documentation, cross-border transfer compliance and retention all require knowing what personal data you hold and where it lives. Each fails independently if the map is wrong.
Where is personal data most commonly missed?
Backups and disaster recovery copies, data warehouses, application logs, email attachments and shared drives, departmental spreadsheet extracts, unmasked test environments, decommissioned systems retained "for history", and third-party processor systems.
How do you keep a data map current?
By attaching it to the processes that change reality — procurement, new integrations, new suppliers and new reports should each update the map as part of approval. Maps maintained as standalone documents are obsolete within a quarter.
What is the most valuable output of a mapping exercise?
Usually the deletion list. Most organizations find systems, extracts and retained datasets that serve no current purpose. Deleting them reduces risk and regulatory obligation at the same time, at no operational cost.
Data Mapping Engagement — Outpace finds every copy of your personal data, including the ones nobody remembers, and builds a register that stays accurate.