Patch management is the least interesting subject in cybersecurity and, measured by damage prevented per pound spent, close to the most valuable. WannaCry made that case in the most public way available: Microsoft shipped MS17-010 on 14 March 2017, the worm arrived on Friday 12 May, and in the intervening eight weeks more than 200,000 computers across at least 100 countries had remained reachable and unpatched. The technical explanation of what happened takes one sentence. The organisational explanation takes considerably longer, and it is the part worth writing down. Because the honest finding from the post-incident reviews was not that anyone had decided patching was unimportant. It was that nobody owned the decision to apply a specific patch to a specific system by a specific date, and in the absence of an owner the default outcome was delay.
Why patch programmes fail, in order of frequency
No complete asset inventory. You cannot patch what you do not know exists. Every organisation that has done this work honestly discovers machines nobody owns: a server under a desk running a departmental application, a kiosk, a device installed by a facilities contractor, a virtual machine spun up for a project that ended. The inventory is not a documentation exercise; it is the precondition for every other control, and it is where the WannaCry post-mortems consistently pointed. Ownership diffusion. Patching a business system requires agreement from whoever runs the application, whoever runs the infrastructure, whoever tests it and whoever can authorise downtime. Each can defer. None can proceed alone. Absent a named accountable owner with authority to schedule the outage, the patch waits for a consensus that never arrives. Windows negotiated per event. Where each maintenance window must be requested and approved individually, the transaction cost of patching exceeds the perceived benefit, and the backlog grows monotonically. Standing pre-approved windows — monthly, published a year ahead, with the business having agreed once rather than every time — change the economics entirely. This is the single highest-leverage process change available. No test path. Teams that cannot validate a patch safely will not apply it quickly. The fear is legitimate: patches do break things. But the answer is not to patch less, it is to be able to patch faster — a representative test environment, a defined smoke test, and a rehearsed rollback. Organisations that invested there moved from quarterly to fortnightly cycles without increasing incidents. Vendor certification treated as a blocker rather than a clock. "The vendor has not certified this patch" is often relayed second-hand by an integrator and is frequently out of date. It should start a timer and an escalation, not end the conversation. No measurement. A programme without a metric cannot improve. Patch compliance percentage alone is misleading; time-to-patch by severity tier, and the age of the oldest unpatched critical vulnerability on an internet-facing system, are the numbers that correlate with actual risk.
What a working programme looks like
The structure is unremarkable, which is why it is so often absent. A complete asset inventory with a named owner per system. Tiering by exposure and criticality — internet-facing first, then endpoints, then internal servers, then the systems that genuinely cannot be touched. Published service levels by severity, in days rather than quarters, agreed with the business rather than imposed by IT. Standing maintenance windows. Automated deployment for endpoints, because manual endpoint patching does not scale and does not happen. A documented exception process with an expiry date, a named approver and a compensating control — not a spreadsheet of permanent carve-outs. And for the systems that genuinely cannot be patched, network segmentation as the compensating control, because if the vulnerability cannot be removed, the reachability must be. That last point is what actually failed in 2017. Flat internal networks were the amplifier: a single unpatched machine reachable from a single infected endpoint became an estate-wide event. Patching reduces the number of vulnerable hosts; segmentation reduces the consequence of the ones you miss. Programmes that treat them as alternatives are choosing badly — they are complements, and the second is what protects you from the inevitable failure of the first.
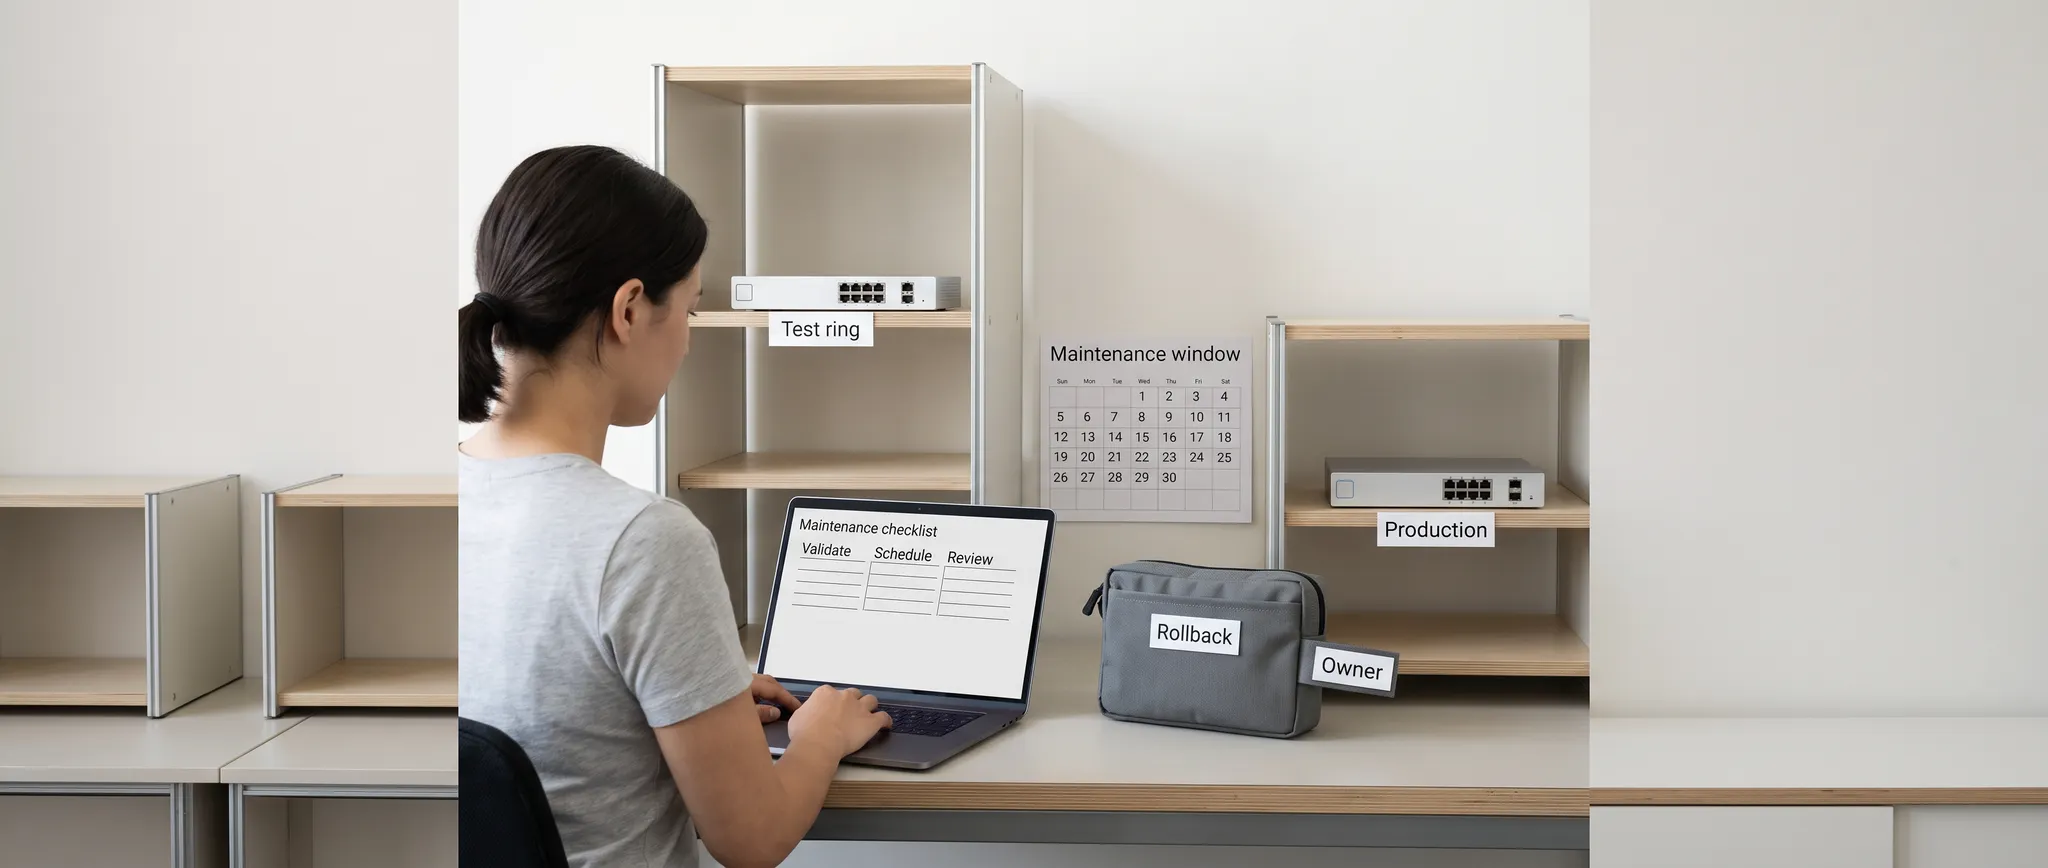
Know the asset and owner
Maintain inventory, exposure and accountable outage authority.
Test and schedule
Use a representative test path, rollback and agreed maintenance window.
Deploy in stages
Use phased rings and inspect the results before wider deployment.
Manage the exception
Record expiry, approver, isolation and a tested compensating control.
Qualitative summary of this article's source text, not a measured outcome or performance estimate.
Practical Guidance for Patch Program Assessment
- Build the asset inventory first and accept that it will be embarrassing. Unowned machines are the population that gets exploited, and they cannot be found from a purchase ledger.
- Name an accountable owner per system with authority to schedule downtime. Diffuse ownership is the mechanism by which patches wait indefinitely.
- Establish standing pre-approved maintenance windows for the year. Negotiating each window separately is the largest single source of patch delay.
- Invest in a test environment and a rehearsed rollback. The goal is not patching less carefully, it is being able to patch faster with confidence.
- Set service levels by severity and exposure, and publish time-to-patch against them. Compliance percentage hides the tail; age of the oldest critical exposure does not.
- Automate endpoint patching with phased rings and a holdback group. Staged rollout catches the patch that breaks something before it reaches everyone.
- Give every exception an expiry date, a named approver and a compensating control. An exception register without dates is a permanent vulnerability list.
- Segment whatever cannot be patched. If the flaw cannot be removed, remove the reachability — this is what limits blast radius when patching fails.
The Regional Dimension
Patch programmes in the Gulf face a distinctive set of constraints, and the generic advice breaks against several of them. The integrator-operated estate comes first. A large share of regional ERP, HR and infrastructure is implemented and maintained by systems integrators under multi-year contracts, which means patch cadence is frequently a contractual matter rather than an operational decision. Two questions are worth answering before any assessment: does the contract specify a patch service level by severity, or does it only oblige the partner to maintain the system in its current state, and who pays for out-of-cycle emergency patching? Many regional organisations discover that urgent patching is a chargeable change request — which introduces a commercial negotiation into the middle of an incident. Equally important: vendor certification claims relayed through a partner are frequently stale. Verify them against the vendor's published support notes directly. Localisation depth sets the regression burden, and it is heavier here than in single-market deployments. A regional ERP instance typically carries Arabic-language document output and bidirectional layout, wage protection system payroll file formats, end-of-service gratuity calculations, GOSI contributions, VAT and Saudi e-invoicing clearance integration, agency and distributor rebate logic, and multi-entity structures spanning free zone and mainland jurisdictions with different activity rules. Each is a regression surface. A patch that is routine elsewhere requires genuine retesting here, which is precisely why the test environment investment pays for itself faster in this region than in the markets where the vendor's own testing covers most of your configuration. The maintenance calendar is genuinely harder to construct. Weekend days differ across GCC markets, which narrows the windows available to a group operating in several of them. Ramadan working hours compress the available downtime further, Hajj and Eid periods restrict change in some sectors, and the retail, logistics and hospitality peaks tied to regional events consume months at a time. A group that has not published a year-ahead window calendar will find that in practice there is never a convenient time, which is how eight-week exposure windows happen. Two further factors. The regulatory position has firmed considerably: national cybersecurity authorities in the UAE and Saudi Arabia, central bank frameworks for financial institutions, and sector requirements in energy, health and telecommunications now make vulnerability and patch management an auditable control with documented service levels rather than an internal aspiration — and the exception register is one of the first artefacts an assessor asks for. And the operational technology layer sets the hard limit: ports, refineries, petrochemical plants, utilities and smelters run control systems with decade-plus lifecycles where patching may be impossible and vendor support may have ended. For those, segmentation, strict access control and monitoring are not compensating controls on the way to patching — they are the permanent answer. The Shamoon campaigns already demonstrated regionally what happens when destructive malware reaches a flat network, which means the segmentation argument lands here without needing a foreign case study.
The objection worth taking seriously
The fair counter-argument is that "patch faster" is advice from people who do not carry availability risk. Patches do break production systems. A finance team that cannot close the month because a database update changed behaviour, a warehouse that cannot ship because a client update broke the scanning application, a payroll run that fails on a government submission format — these are real costs, borne by named people, and the incentives are asymmetric. An operations manager who prevents a patch-induced outage is doing their job; one who prevents a breach nobody attempted gets no credit. Recommending aggressive patch cadence without funding the test environment, the rollback capability and the staged deployment rings is recommending that someone else absorb the risk. There is also a proportionality problem with the full framework. Asset management tooling, vulnerability scanning, test environments, phased deployment rings, governance and reporting is a programme with staff. An organisation with three IT people and a hundred users cannot run it, and being told to do so leads to nothing being done. Their realistic minimum is four things: automatic updates enabled on endpoints, internet-facing systems patched within days, anything unpatchable segmented or disconnected, and an annual review of what is still running unsupported software. That set addresses the large majority of realistic exposure. And a point of intellectual honesty about 2017 itself: patching alone would have stopped WannaCry, but it would not have stopped NotPetya six weeks later, which combined the same exploit with stolen administrator credentials and compromised fully patched machines. Patch management is necessary and insufficient. An organisation that concluded from 2017 that patching was the answer and stopped there drew half a lesson — privileged access control and segmentation were the other half, and the second incident proved it.
Common Questions
What is the right time-to-patch target?
Tiered by exposure: days for internet-facing critical vulnerabilities, a few weeks for endpoints and internal servers, and a documented compensating control for anything that cannot meet either. The specific numbers matter less than having them agreed with the business and measured publicly.
Which metric best reflects real risk?
The age of the oldest unpatched critical vulnerability on an internet-facing system. Compliance percentages average away exactly the exposures that get exploited.
How should unpatchable systems be handled?
Segment them, restrict access to a named list, monitor them more closely than anything else, and record the exception with an owner and a review date. If it cannot be fixed, it must be isolated — and the isolation needs testing, because most organisations discover their segmentation is more permeable than the diagram suggests.
Has AI changed patch urgency?
It has shortened the window on both sides. Exploit development against newly disclosed vulnerabilities is faster and more automated, and internet-wide scanning for exposed vulnerable systems is cheap and continuous — so the eight weeks that MS17-010 allowed is not a window anyone should plan around now. Prioritisation has genuinely improved: exploit-prediction scoring and known-exploited-vulnerability catalogues let teams distinguish the handful of flaws being actively used from the thousands that are theoretical, which is the difference between a triageable queue and an unusable one. AI also helps with the regression problem that makes regional patching slow, by generating test coverage for customised configurations and flagging which localisations a given change could affect. The structural conclusion is unchanged but tighter: the constraint was never knowing that a patch existed, it was owning the decision to apply it and having the capability to do so safely. Faster attacker tooling makes that ownership gap more expensive, not more complicated.
Patch Program Assessment — standing maintenance windows, a named owner per system and segmentation for what cannot be patched; the eight-week window was an ownership failure, not a technical one.